A growth team decides how much it wants to spend to acquire a customer. Then someone builds an LTV model to show that the spend makes sense. That is how a useful spreadsheet can quietly become a justification tool. LTV modeling in ecommerce should work the other way around. Start with what customers have actually done, then make a limited prediction about what they may do next. The model should show where the evidence ends and where the assumptions begin.
The best model is not the most complex one. For a mid-sized business, a cohort-based model with contribution margin, a capped forecast and regular validation is usually easier to understand and harder to manipulate.
Key Takeaways
- LTV models should separate observed value from future predictions and clearly show where assumptions begin.
- It accounts for variable costs instead of looking only at revenue.
- A capped forecast limits the effect of uncertain assumptions about long-term customer behavior.
- Hold back a newer cohort, compare predicted LTV with actual LTV, and report the forecast error.
- A clear cohort-based model that is regularly tested is more useful than a complex model that nobody can explain or audit.
What is LTV, and which versions are used?
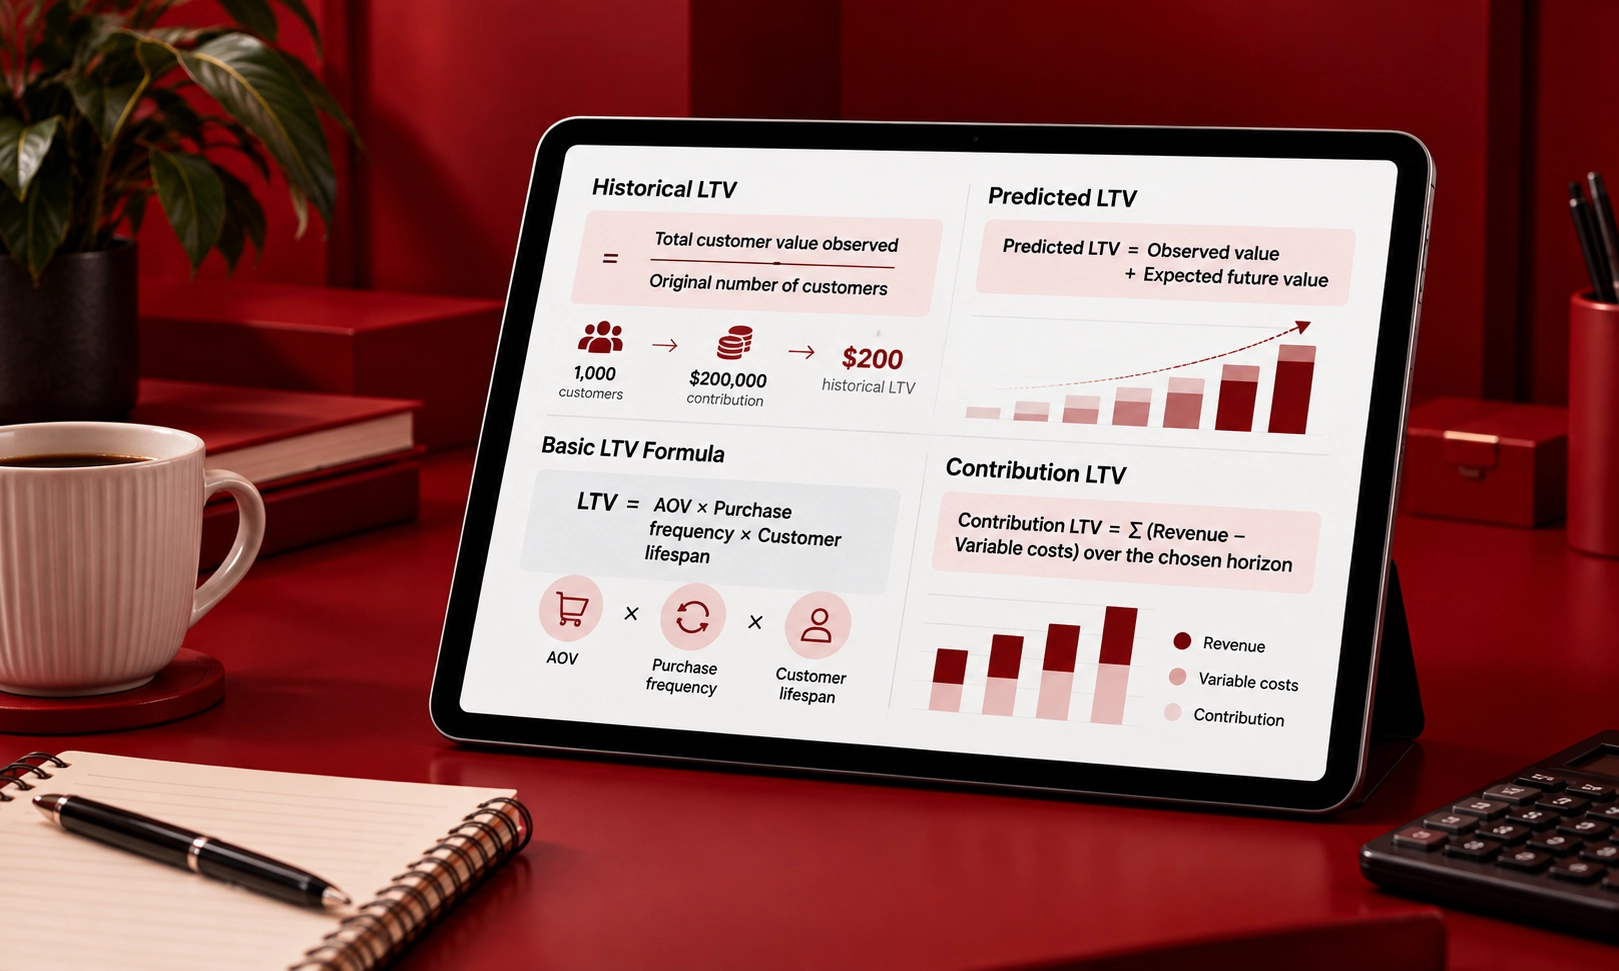
Customer lifetime value can be measured from past behavior or estimated for the future. The important thing is to keep those two ideas separate. Historical LTV measures value already observed:
Historical LTV = Total customer value observed ÷ Original number of customers
If 1,000 customers have generated $200,000 in contribution margin, then historical LTV is $200. Predicted LTV adds expected future value:
Predicted LTV = Observed value + Expected future value
The future part depends on assumptions about repeat purchases, retention and contribution. A basic customer lifetime value calculation uses:
LTV = AOV × Purchase frequency × Customer lifespan
This is useful for a quick estimate but can become weak when one average customer is assumed to represent every cohort. For acquisition decisions, a contribution-based measure is more useful:
Contribution LTV = Σ(Revenue − Variable costs) over the chosen horizon
That accounts for the money left after costs that vary with each order. Revenue-based LTV can look large while leaving little contribution to recover CAC.
This article uses cohort-based contribution LTV with a capped horizon because it keeps the model close to observed behavior without pretending the business can predict a customer’s entire future.
Why are most LTV models wrong in the same direction?
The biggest problem is often motivation rather than mathematics. If a business wants to approve a higher CAC, it can be tempting to build an LTV model around that target. A long customer lifespan, strong retention assumption and distant future purchases can then make the answer look better than the evidence supports.
Survivorship bias
A model can overstate LTV when it looks only at customers who remain active instead of keeping the original cohort as the denominator. Customers who stopped buying still belong in the original cohort.
Long tails
A small group of customers may keep buying for years. Extending that behavior too far can add a large amount of uncertain value to the model.
No discounting
No discounting can also overstate the practical value of distant cash flows. Money received later is not equivalent to money available now when the model is used for investment decisions.
Missing costs
Returns, refunds and variable costs can inflate an LTV number when the model starts with sales and stops there. A spreadsheet can therefore be mathematically neat while still being economically optimistic.
Which LTV method fits a mid-sized business?
There are four useful approaches, from simple to complex.
| Method | Data needed | What it gives you | Where it breaks |
| Historical cohort average | Orders and acquisition cohorts | Observed customer value | Does not fully predict the future |
| Capped cohort curve | Cohort value over time | Simple forward estimate | Depends on the forecast horizon |
| Probabilistic model | Detailed purchase history | Future purchase probabilities | More assumptions to explain |
| Machine learning | Large customer-level dataset | Individual predictions | Can overfit and become hard to audit |
Historical cohort average is the easiest starting point. Group customers by acquisition month and measure contribution as each cohort ages. This shows what has actually happened.
A capped cohort curve takes that evidence and estimates future value only to a defined point. It is useful when a business has enough historical cohorts to see a repeatable pattern.
Probabilistic models estimate future purchasing behavior from individual transaction histories. They can be useful when repeat purchasing is frequent and the business has enough data to support the assumptions.
Machine learning can combine many customer signals to predict future value. It can be useful for individual customer decisions but adds complexity that many mid-sized businesses do not need for basic LTV planning.
For most mid-sized ecommerce businesses, the default should be a cohort-based contribution model with a capped horizon. It is simple enough for a growth team to maintain and detailed enough to show what is observed versus predicted.
How far ahead should an LTV model predict?
Predict only as far as the data can reasonably support. A capped horizon prevents a small assumption about long-term retention from becoming a large part of the LTV number. The right cap depends on the buying cycle and the maturity of your existing cohorts.
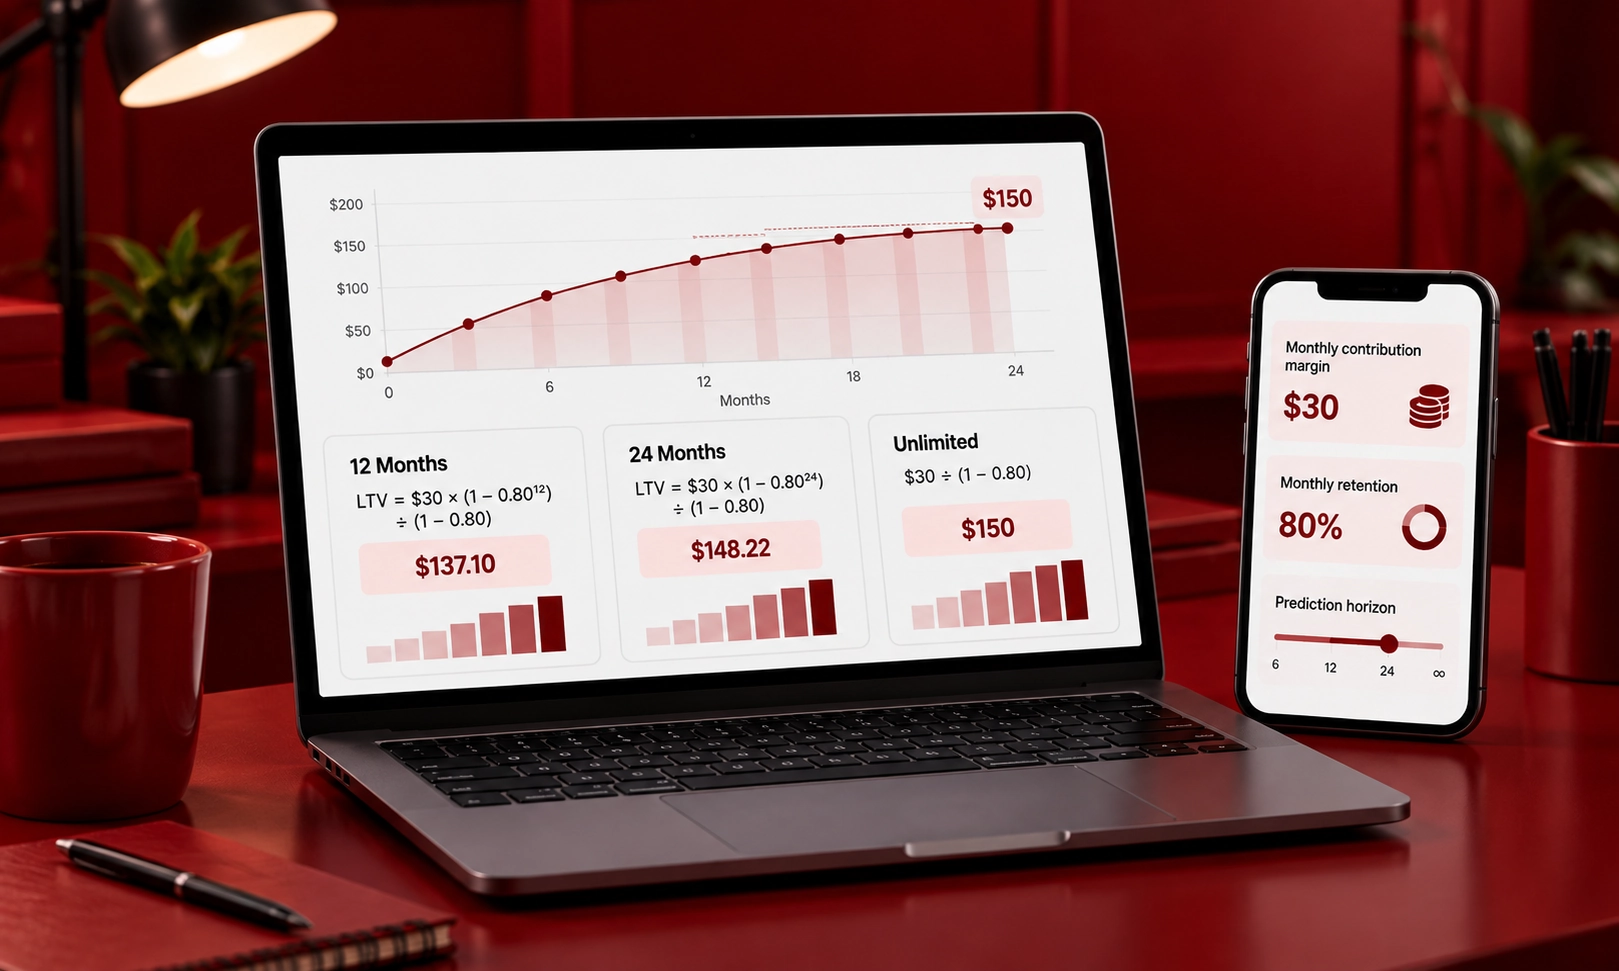
Consider a simple example. Suppose contribution margin is $30 per active customer per month and monthly retention is 80%.
For 12 months:
LTV = $30 × (1 − 0.80¹²) ÷ (1 − 0.80)
LTV = $137.10
For 24 months:
LTV = $30 × (1 − 0.80²⁴) ÷ (1 − 0.80)
LTV = $148.22
An unlimited version approaches:
$30 ÷ (1 − 0.80) = $150
The difference looks small here. But when LTV is multiplied across thousands of customers, it can materially change an acquisition decision.
Test the cap against older cohorts that already have more complete data. If a 12-month forecast consistently matches mature cohort behavior better than a 36-month forecast, then the shorter horizon has stronger evidence behind it.
How do you validate an LTV model honestly?
Do not test a model only against the customers used to build it. Instead, hold back a newer cohort. Build the model using earlier cohorts, then predict the held-out cohort. Once enough time has passed, compare the prediction with what actually happened. A simple error formula is:
Forecast error = Actual LTV − Predicted LTV
You can also express the difference as a percentage:
Percentage error = (Actual LTV − Predicted LTV) ÷ Predicted LTV × 100
If the model predicts $200 and the cohort produces $180:
($180 − $200) ÷ $200 × 100 = −10%
The model overestimated LTV by 10%. That error should be visible in the model review. If the model is always optimistic, changing the spreadsheet to produce a higher number is not validation.
If you never report the error, you are not modelling. You are asserting. Revalidate at least quarterly. Recheck sooner when pricing, product mix, acquisition channels or customer behavior changes significantly.
How should you use LTV alongside CAC?
The ltv cac ratio is simple:
LTV:CAC = LTV ÷ CAC
If contribution LTV is $300 and CAC is $100:
$300 ÷ $100 = 3:1
The problem is that the ratio does not tell you when the money comes back. That is why acquisition payback should sit beside it. Track cumulative contribution from the customer until it covers the CAC. For example, if CAC is $100 and a customer contributes $40 in month one, $30 in month two and $25 in month three, then cumulative contribution reaches $95. If month four adds $2,0 then the customer passes $100 and has reached payback.
The ratio and payback answer different questions. The ratio shows the relationship between total value and acquisition cost. Payback shows how quickly the acquisition cost is recovered. There is no universal LTV: CAC ratio that works for every business. Some current ecommerce guidance cites 3:1 as a common benchmark but also notes that businesses vary. Treat that figure as a reference point rather than a rule.
The separate unit economics and CAC benchmark pieces should cover the wider economics. Here the important point is to make sure the LTV number going into those decisions is defensible.
What should a maintainable LTV model look like?
Keep the model simple enough that one person can explain every major formula. Use monthly acquisition cohorts in the rows and customer age across the columns. Track customers, orders, revenue, variable costs and contribution margin. Then calculate:
Contribution margin = Revenue − Variable costs
Cumulative contribution LTV = Total cohort contribution margin ÷ Original cohort customers
Keep the forecast horizon visible. Do not hide a two-year assumption inside a formula that nobody checks. Each month, check whether newer cohorts are following the older curve. Check whether margins have changed and whether the customer mix is still comparable.
Do not rebuild the model every time one cohort behaves differently. Revalidate the assumptions quarterly and change them when the evidence supports a change.
The read
A growth team should treat predicted LTV as a decision input, not a fact. The farther you forecast, the more the number depends on assumptions rather than observation. That does not make forecasting useless. It means the model should make that uncertainty visible. For a mid-sized ecommerce business, I would rather maintain a simple cohort model that is tested every quarter than build a complex model that nobody can explain.
The fix this week is simple: add a holdout cohort and a capped forecast to the existing LTV model. Put predicted LTV beside actual LTV and report the error. That tells you whether the model is learning from customers or simply defending a decision already made. Want more growth analysis? Subscribe to the daily brief.
Frequently Asked Questions
How do you calculate customer lifetime value?
A basic customer lifetime value formula is LTV = AOV × purchase frequency × customer lifespan. For acquisition decisions, a contribution-based version is more useful because it accounts for variable costs. A cohort model can then track actual contribution and add a limited forecast.
What is a good LTV to CAC ratio?
There is no universal ratio that works for every business. A 3:1 ratio is often cited as a reference benchmark, but the right level depends on margins, cash flow, business model and payback. Always check the ratio alongside acquisition payback and make sure LTV and CAC use compatible definitions.
How far ahead should an LTV model predict?
Use a horizon that your data can support. A capped forecast is safer than an open-ended one because it limits the effect of uncertain long-term assumptions. Compare different caps against older cohorts and choose the horizon that produces forecasts you can actually validate.
Should LTV be based on revenue or margin?
Revenue can show the sales value generated by customers. Contribution margin is more useful when LTV is compared with CAC because it shows the money left after variable costs. For growth investment decisions, margin-based LTV gives a more useful view of what the customer can contribute.
What is cohort-based LTV?
Cohort-based LTV groups customers by a shared starting point such as their first purchase month. You then track each group as it ages. This prevents newer customers with less time to buy from being blended with older customers who have had much longer to generate value.
How do you validate an LTV model?
Build the model using earlier cohorts and hold back a newer cohort for testing. Predict the newer cohort’s value, then compare it with the actual result once enough time has passed. Report the error and repeat the process regularly so the model can be checked against changing customer behavior.