You open an online store and see a recommendation for something you already bought yesterday. An email uses your name but recommends a product that makes no sense. A brand suddenly changes its message because an algorithm has decided the kind of customer that you are.
These are not always data-quality problems. They can happen when AI personalization at scale takes a real signal and turns it into a conclusion that was never justified. The system may know that you bought, clicked or browsed, but that does not mean it knows why you did it.
The problem gets bigger as AI personalization scales. AI can make more decisions across more customers, channels and moments, but it can also spread a bad assumption just as efficiently.
Key Takeaways
- Scale multiplies both useful AI personalization and personalization errors.
- Recent behavior is evidence of an action, not automatically evidence of identity or intent.
- The deeper an AI system moves from observed behavior to inferred traits, the more governance it needs.
- AI Personalization should be measured for errors and customer experience, not only conversion lift.
- A strong fallback can be safer than forcing a personalized message when the evidence is weak.
The central failure happens in the gap between what the system knows and what it assumes.
What Scale Actually Changes
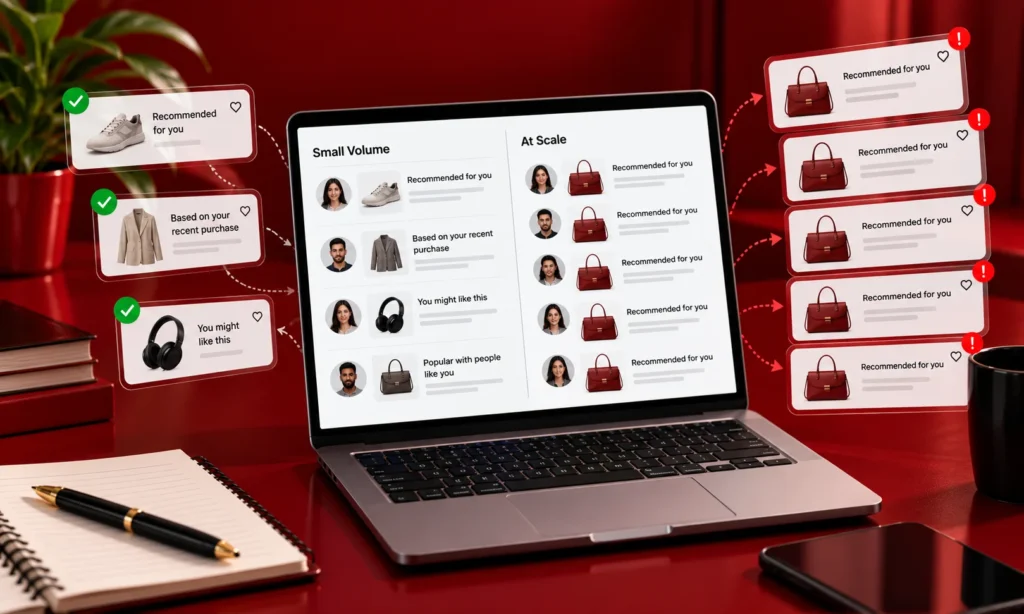
At small volumes, people can catch bad personalized messages before they reach many customers. At scale, the same decision can be made thousands or millions of times before anyone notices the pattern. That changes the cost of being wrong.
Why a tolerable error becomes a volume problem
A single incorrect recommendation may be harmless. A system that makes the same mistake across 100,000 interactions creates a different problem. The mistake becomes part of the customer experience rather than an isolated exception.
This is the reason AI personalization at scale needs more than better automation. It needs controls that identify when the system is operating outside the evidence available to it.
The asymmetry most business cases miss
A correct personalized message may be only slightly better than a useful generic message. A wrong personalized message can be much worse because it tells the customer that the brand has misunderstood them while acting confident about that conclusion.
That difference matters. Research on AI personalization shows that personalized communication can increase purchase behavior while also increasing perceptions of intrusiveness. The commercial result can look positive even when part of the customer experience is moving in the wrong direction.
The Five Failure Modes
These five failure modes cover the main ways AI personalization can move from useful relevance to an unsupported assumption. They also provide a practical vocabulary for reviewing one to one AI personalization and dynamic creative personalization before those systems operate at high volume.
| Failure mode | What goes wrong | Main cost |
| The Stale Signal | Old information is treated as current | Irrelevant experience |
| The Single Purchase Assumption | One action becomes a customer identity | Narrow targeting |
| The Sensitive Inference | The system guesses something personal | Trust and privacy risk |
| The Identity Collision | Activity from different people is combined | Wrong recommendations |
| The Confident Gap | The system fills missing information with an assumption | False personalization |
The Stale Signal
The data was once true but is no longer true. A recent purchase may remove a product from consideration. A browsing session may reflect temporary research rather than genuine interest. A customer’s circumstances can change faster than a profile is updated.
The problem is not that the original signal was false. The problem is treating historical evidence as permanent evidence. At scale, stale signals can repeatedly trigger the same outdated message.
The Single Purchase Assumption
One transaction becomes a description of the whole customer. Buying a gift, trying a new category or making a one-time purchase can cause recommendation systems to overvalue that event.
A stronger AI personalization system considers the broader pattern rather than letting one unusually strong signal dominate the profile. Recommendation research also points to the importance of calibration so that systems do not repeatedly narrow their expression around a limited slice of a customer’s interests.
The Sensitive Inference
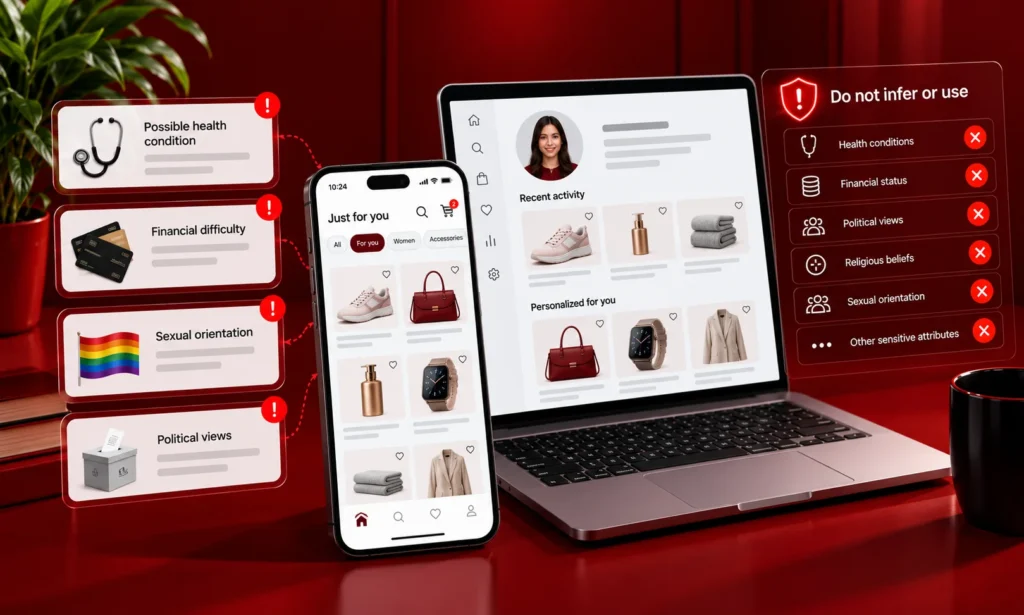
The system combines ordinary signals and concludes something the customer never explicitly shared. Health status, political views, religious beliefs or sexual orientation are examples of areas where inference can become particularly sensitive.
Accuracy stops being a sufficient defense at this point. Privacy regulators have made clear that certain sensitive information can be protected even when it is inferred rather than directly provided. The cost can therefore extend beyond a poor recommendation into a serious privacy and trust problem.
The Identity Collision
Two people use the same device, account or household profile, but the system treats their activity as belonging to one person. One person’s browsing or purchases can then influence recommendations shown to another.
This creates a particularly confusing experience because every individual signal may look legitimate. The error happens when the system connects those signals to the wrong identity.
The Confident Gap
The system lacks an important piece of information but personalizes as if it has it. Instead of saying “we do not know,” the model fills the gap using patterns from other signals. That can make AI personalization look impressive while actually reducing accuracy. A fluent message does not prove that the underlying assumption is supported.
Why the Sensitive Inference Is the Expensive One
The most dangerous AI personalization error is not always an incorrect product recommendation. Sometimes it is an accurate-looking conclusion about a person that the brand had no good reason to make or use.
When being right is as bad as being wrong
Imagine a system inferring that someone may have a health condition from their browsing behavior or treating financial difficulty as a targeting signal. Even if the inference happens to be correct, using it can make the interaction feel invasive.
The ICO treats profiling that infers sensitive information such as health, political views, religious beliefs or sexual orientation as a serious privacy issue.
The EDPB has also emphasized that inferred information can fall within special-category protections and that its correctness does not automatically make the processing acceptable. The practical lesson is simple: being right does not make every inference appropriate to use.
What an inference guardrail looks like
An automation guardrail should define which customer attributes the system may not infer or act on, even when the model appears confident. That list should have a clear owner and a documented approval process for changes.
This is part of model governance, not just prompt design. The organization should know which signals can drive AI personalization, which conclusions are prohibited and when human review is required before a high-risk use case reaches customers.
Where Dynamic Creative Holds Up
Not every form of AI personalization carries the same risk. The safest uses tend to stay close to the work of the customer rather than making deeper claims about who the customer is.
What personalizes reliably
Format, language, location, product category and recent browsing behavior are generally easier to connect to an observable customer action. A system can change a product image based on the category being viewed or adjust language based on a known preference without trying to infer a private characteristic.
This makes dynamic creative AI personalization useful when it responds to clear context. The closer the decision stays to an observable signal, the easier it is to explain why the customer received that experience.
Personalize what you observed, not what you concluded
A useful boundary is to personalize around evidence rather than interpretation. “You viewed running shoes” is an observed action. “You are a serious runner” is a conclusion. That distinction becomes more important as AI personalization gets deeper.
Research suggests AI personalization can be beneficial, but its impact depends on factors such as the type of data used and the degree of personalization. The goal is therefore not to make every interaction as personal as possible. It is to make the additional AI personalization worth the additional inference.
The Measurement Problem Underneath It
Most AI personalization programmes make the business outcome easy to see. Conversion rate, revenue or engagement can be compared against a control group. The harder question is how many individual personalized interactions were actually wrong.
Why the average hides the wrong messages
A campaign can produce positive average results while still generating poor experiences for a smaller group. If most customers receive useful recommendations while a minority receive obviously irrelevant or intrusive ones, the overall conversion number may hide the failure.
This is especially important because AI personalization can create competing effects. Recent field research found that personalized AI communication improved purchase behavior while also increasing perceived intrusiveness. Measuring only the purchase outcome would miss half of that story.
What to measure instead
A practical personalization error rate can measure the share of sampled interactions judged irrelevant, inappropriate or unsupported by the available evidence. It should sit alongside business lift rather than replace it. For recommendation systems, relevance and coverage metrics can add another layer of measurement.
Human review can then examine the errors that automated metrics miss. Production monitoring also matters because AI systems can drift after deployment and their behavior can change as customer behavior or operating conditions change. A useful measurement set is therefore:
- Business lift: Did AI personalization improve the intended outcome?
- Relevance: Was the recommendation or message appropriate?
- Error rate: How often was the personalization wrong or unsupported?
- Intrusiveness: Did the personalization feel excessive or unexpected?
- Drift: Is performance changing after deployment?
This gives teams a clearer picture than conversion lift alone.
How to Put a Floor Under It
The goal of guardrails is not to remove automation. It is to stop automation from turning uncertain signals into confident customer-facing decisions. A practical personalization guardrail checklist:
- Age limit on signals: Give different signals an appropriate freshness window rather than treating every historical action as equally relevant.
- Suppression list of inferences: Block sensitive or unsupported conclusions from driving personalization.
- Rule for shared devices: Avoid treating mixed household or shared-device activity as one clear customer identity.
- Fallback that is good rather than empty: When evidence is weak, use a useful generic experience instead of forcing personalization.
- Human sample of output every week: Review a defined sample of live personalized interactions to catch errors that automated metrics miss.
These controls work best when they are built into the workflow rather than added after a problem appears. NIST guidance emphasizes defined human oversight, ongoing monitoring, regular evaluation and the ability for AI systems to fail safely when they operate beyond their limits.
Prompt workflows can support this process by separating generation from review. For example, one step can create the message, another can check the personalization evidence, another can review risk rules and a final step can verify the output before release.
The important point is that a workflow cannot turn bad evidence into good evidence. It can only make the checking process more consistent.
The Read
AI personalization at scale works best when the system stays close to evidence it can actually support. The biggest risk appears when a real customer action becomes a broader conclusion about identity, intent or personal circumstances.
That does not mean brands should abandon one to one personalization. It means deeper personalization has to earn its place. If the extra inference adds little value while increasing the chance of an intrusive or incorrect experience, the smarter choice may be a simpler message.
The practical move this week is to find one personalization rule that depends on an assumption rather than an observed signal. Turn it off temporarily, compare the result against your current experience and see whether the extra personalization is actually earning its place.